Pro*_*o Q 4 python algorithm artificial-intelligence structure machine-learning
MuZero是一种深度强化学习技术,刚刚发布,我一直在尝试通过查看其伪代码和 Medium 上的这篇有用教程来实现它。
然而,我对伪代码训练期间如何处理奖励感到困惑,如果有人能够验证我是否正确地阅读了代码,那就太好了,如果我是,请解释为什么这个训练算法有效。
这是训练函数(来自伪代码):
def update_weights(optimizer: tf.train.Optimizer, network: Network, batch,
                   weight_decay: float):
  loss = 0
  for image, actions, targets in batch:
    # Initial step, from the real observation.
    value, reward, policy_logits, hidden_state = network.initial_inference(
        image)
    predictions = [(1.0, value, reward, policy_logits)]

    # Recurrent steps, from action and previous hidden state.
    for action in actions:
      value, reward, policy_logits, hidden_state = network.recurrent_inference(
          hidden_state, action)
      predictions.append((1.0 / len(actions), value, reward, policy_logits))

      hidden_state = tf.scale_gradient(hidden_state, 0.5)

    for prediction, target in zip(predictions, targets):
      gradient_scale, value, reward, policy_logits = prediction
      target_value, target_reward, target_policy = target

      l = (
          scalar_loss(value, target_value) +
          scalar_loss(reward, target_reward) +
          tf.nn.softmax_cross_entropy_with_logits(
              logits=policy_logits, labels=target_policy))

      loss += tf.scale_gradient(l, gradient_scale)

  for weights in network.get_weights():
    loss += weight_decay * tf.nn.l2_loss(weights)

  optimizer.minimize(loss)
reward我对损失特别感兴趣。请注意,损失从 中获取其所有值predictions。第一个reward添加的predictions是来自network.initial_inference函数的。之后还有len(actions)更多的奖励加入predictions,都是来自于network.recurrent_inference功能。
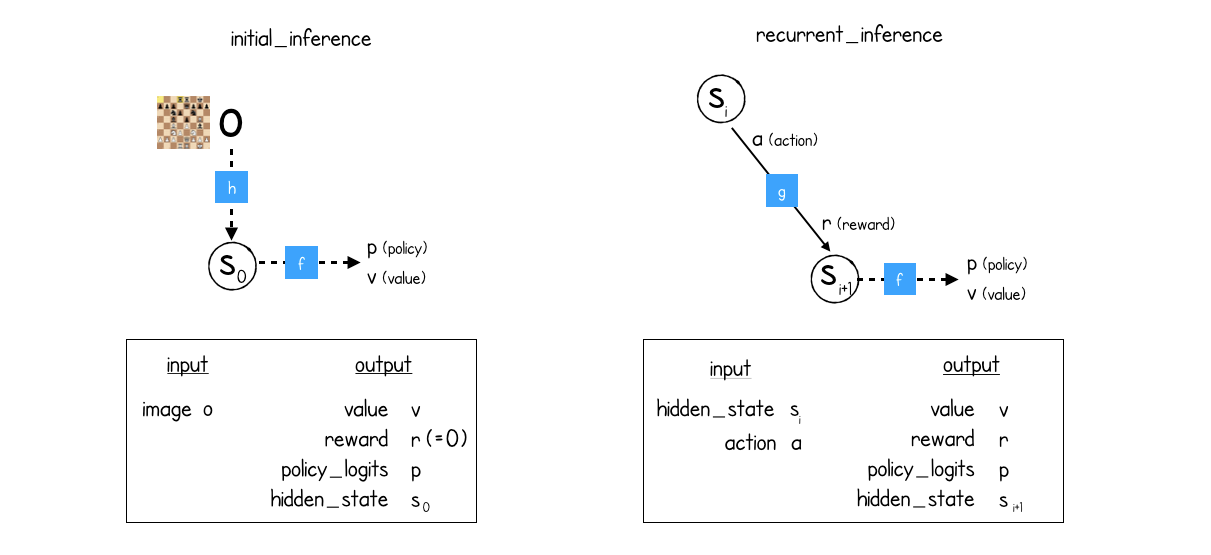
根据教程initial_inference,recurrent_inference函数由 3 个不同的函数组成:
该initial_inference函数接受外部游戏状态,使用该representation函数将其转换为内部状态,然后prediction对该内部游戏状态使用该函数。它输出内部状态、策略和值。
该recurrent_inference函数接受内部游戏状态和动作。它使用该dynamics函数从旧的游戏状态和动作中获取新的内部游戏状态和奖励。然后,它将prediction函数应用于新的内部游戏状态,以获得该新内部状态的策略和值。因此,最终的输出是一个新的内部状态、奖励、策略和值。
然而,在伪代码中,该initial_inference函数还返回奖励。
我的主要问题:这个奖励代表什么?
在教程中,他们只是隐含地假设initial_inference函数的奖励为 0。(请参阅教程中的这张图片。)那么这是怎么回事呢?难道真的没有奖励,所以initial_inference奖励总是返回0吗?
让我们假设情况确实如此。
在此假设下,列表中的第一个奖励将是函数将返回的奖励predictions0 。initial_inference然后,在损失中,这个0将与列表的第一个元素进行比较target。
target创建方式如下:
  def make_target(self, state_index: int, num_unroll_steps: int, td_steps: int,
                  to_play: Player):
    # The value target is the discounted root value of the search tree N steps
    # into the future, plus the discounted sum of all rewards until then.
    targets = []
    for current_index in range(state_index, state_index + num_unroll_steps + 1):
      bootstrap_index = current_index + td_steps
      if bootstrap_index < len(self.root_values):
        value = self.root_values[bootstrap_index] * self.discount**td_steps
      else:
        value = 0

      for i, reward in enumerate(self.rewards[current_index:bootstrap_index]):
        value += reward * self.discount**i  # pytype: disable=unsupported-operands

      if current_index < len(self.root_values):
        targets.append((value, self.rewards[current_index],
                        self.child_visits[current_index]))
      else:
        # States past the end of games are treated as absorbing states.
        targets.append((0, 0, []))
    return targets
targets该函数返回的结果成为函数target中的列表update_weights。所以第一个值targets是self.rewards[current_index]。这self.rewards是玩游戏时收到的所有奖励的列表。唯一一次编辑是在此函数内apply:
  def apply(self, action: Action):
    reward = self.environment.step(action)
    self.rewards.append(reward)
    self.history.append(action)
该apply函数仅在此处被调用:
# Each game is produced by starting at the initial board position, then
# repeatedly executing a Monte Carlo Tree Search to generate moves until the end
# of the game is reached.
def play_game(config: MuZeroConfig, network: Network) -> Game:
  game = config.new_game()

  while not game.terminal() and len(game.history) < config.max_moves:
    # At the root of the search tree we use the representation function to
    # obtain a hidden state given the current observation.
    root = Node(0)
    current_observation = game.make_image(-1)
    expand_node(root, game.to_play(), game.legal_actions(),
                network.initial_inference(current_observation))
    add_exploration_noise(config, root)

    # We then run a Monte Carlo Tree Search using only action sequences and the
    # model learned by the network.
    run_mcts(config, root, game.action_history(), network)
    action = select_action(config, len(game.history), root, network)
    game.apply(action)
    game.store_search_statistics(root)
  return game
对我来说,看起来每次采取行动都会产生奖励。因此列表中的第一个奖励self.rewards应该是在游戏中采取第一个行动的奖励。
current_index = 0如果在 中,问题就很清楚了self.rewards[current_index]。在这种情况下,predictions列表中的第一个奖励将为 0,因为它总是如此。然而,targets列表中,将有完成第一个动作的奖励。
所以,对我来说,奖励似乎是错位的。
如果我们继续,列表中的第二个奖励将是完成第一个predictions操作的奖励。然而,列表中的第二个奖励将是游戏中存储的完成第二个动作的奖励。recurrent_inferencetargets
因此,总的来说,我有三个相互关联的问题:
initial_inference?(它是什么?)predictions未targets对齐?(即,中的第二个奖励predictions实际上应该与中的第一个奖励相匹配吗targets?)(另一个需要注意的好奇心是,尽管存在这种错位(假设存在错位),但 和predictionslength的长度确实相同。目标长度由上面函数中的targets行定义。上面,我们还计算了 的长度为. And是由函数中定义的(参见伪代码)。因此,两个列表的长度相同。)for current_index in range(state_index, state_index + num_unroll_steps + 1)make_targetpredictionslen(actions) + 1len(actions)g.history[i:i + num_unroll_steps]sample_batch
这是怎么回事?
作者在此。
初始推理的奖励代表什么?
最初的推论“预测”了最后观察到的奖励。这实际上没有任何用途,但使我们的代码更简单:预测头总是可以简单地预测紧邻的前一个奖励。对于动态网络,这将是在应用作为动态网络输入给出的动作后观察到的奖励。
游戏开始时没有最后观察到的奖励,因此我们将其设置为 0。
伪代码中的奖励目标计算确实是错位的;我刚刚将新版本上传到 arXiv。
以前常说的地方
      if current_index < len(self.root_values):
        targets.append((value, self.rewards[current_index],
                        self.child_visits[current_index]))
      else:
        # States past the end of games are treated as absorbing states.
        targets.append((0, 0, []))
它应该是:
      # For simplicity the network always predicts the most recently received
      # reward, even for the initial representation network where we already
      # know this reward.
      if current_index > 0 and current_index <= len(self.rewards):
        last_reward = self.rewards[current_index - 1]
      else:
        last_reward = 0

      if current_index < len(self.root_values):
        targets.append((value, last_reward, self.child_visits[current_index]))
      else:
        # States past the end of games are treated as absorbing states.
        targets.append((0, last_reward, []))
希望有帮助!